Linear Models: a Brief Theory#
Linear regression#
Linear models and their relatives (t-tests, ANOVA, mixed models) are the workhorses of scientific data analysis. You have almost certainly used them.
They are also the ideal starting point for understanding predictive modelling — not because predictive modelling is a different kind of mathematics, but because it asks a different question of the same mathematics. This page refreshes the essentials so that the next page can put them to work, and run straight into the first serious problem.
A linear model describes a target variable \(y = (y_1, \dots, y_n)\), measured on \(n\) observations, as a constant \(\beta_0\) (the intercept) plus a multiple of a predictor variable \(x\), plus whatever is left over:
The leftovers \(\varepsilon_i\) are the residuals, and the coefficients are chosen to make them as small as possible. “As small as possible” has to be made precise, and the usual choice is the method of least squares: pick the \(\beta\) that minimizes the sum of squared residuals.
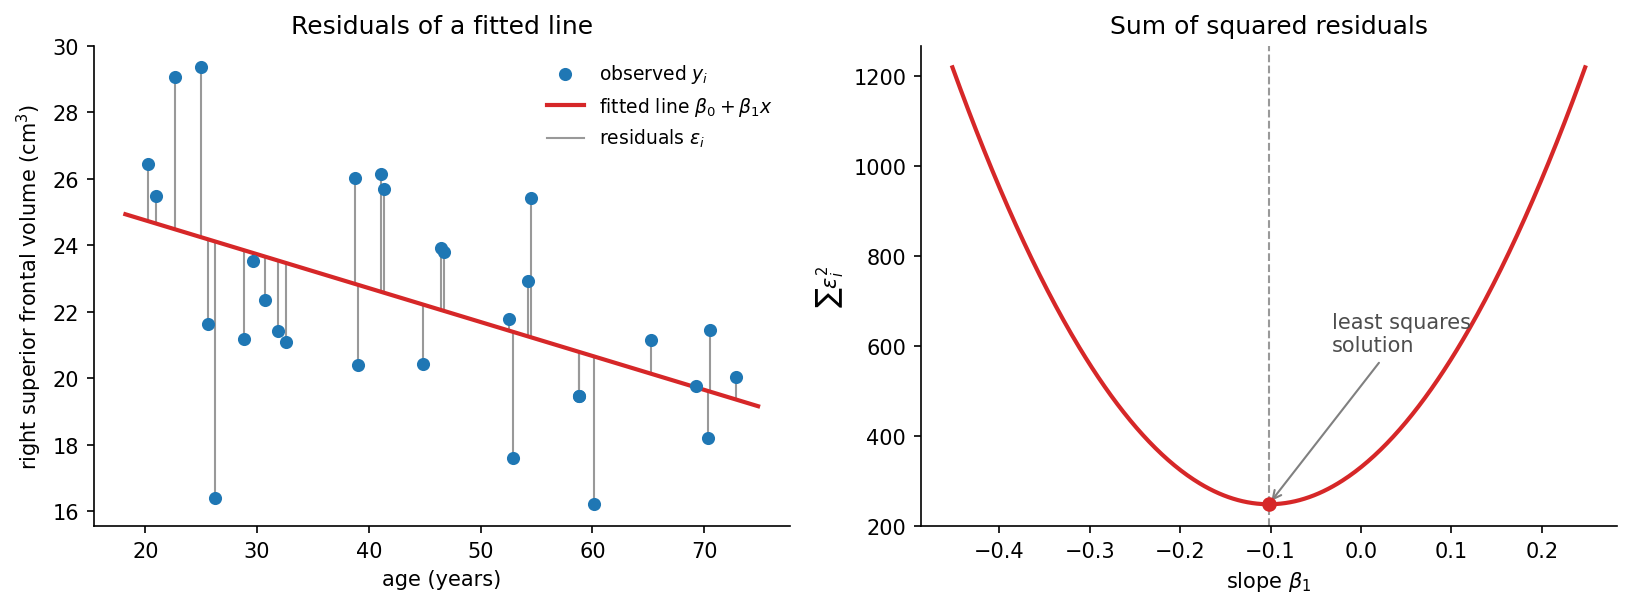
Fig. 1 Least squares in one picture. (Note the axes: here volume is modelled from age, the reverse of the prediction task the rest of the book sets itself — it makes the line easier to read.) Each vertical grey line is one residual \(\varepsilon_i\): the distance between an observed value and what the line predicts for it. The fitted line (red) is the one line, out of all possible lines, that makes the sum of the squares of those distances as small as it can be. The panel on the right shows that sum as a function of the slope: it is a parabola with a single minimum, which is why the solution is unique and can be computed directly.#
Linear regression extends without any conceptual change to several predictors at once (multiple linear regression):
The aim and the method are unchanged: we decompose the target variable into a weighted sum — a linear combination — of the predictors, as close to the target as possible. Collecting the predictors into an \(n \times p\) matrix \(\boldsymbol{X}\) (one row per observation, one column per predictor, plus a column of ones for the intercept) and the coefficients into a vector \(\boldsymbol{\beta}\), the quantity to minimize is
Note
We will return to this equation in chapter 4, where adding a single extra term to it turns a linear model into a machine learning model.
The stronger the association between \(\boldsymbol{y}\) and \(\boldsymbol{X}\), the more closely the model can match them and the smaller the residuals will be. This is why fitting a linear model is so commonly used to quantify an association, through \(R\), \(R^2\), t- and p-values.
Note
Linear regression extends easily to categorical predictors, which is how it reproduces ANOVA and related tests, and to categorical targets (logistic and multinomial regression). Everything in this book applies to those cases too; we stay with a continuous target because it keeps the performance measures simple to read.
Two questions, one model#
Here is the distinction that the whole book rests on. Given a fitted model, you can ask:
an inferential question: is the association between this predictor and the target larger than one would expect by chance? This is answered by a p-value, and it is a statement about a population, conditional on assumptions about how the data were generated.
a predictive question: given the predictors of a person I have never seen, how close will my guess of their target value be? This is answered by a prediction error, and it is a statement about individuals.
They are not the same question, and — as we will see repeatedly — a model can do very well on one and disastrously on the other. Shmueli [6] is the classic treatment of the distinction, and is worth reading alongside this book.
Predictions#
Once the model is fitted, predictions \(\hat{y}\) for arbitrary values of the predictors are obtained by plugging them into the equation:
To judge how good those predictions are we need to summarize the errors in one number. Two measures are used throughout this book:
Both are in the units of the target — years, in our case — which makes them easy to interpret. The mean absolute error (MAE) is the average size of a miss. The root mean squared error (RMSE) squares the errors before averaging, so it is dominated by the few worst predictions; it is never smaller than the MAE, and the gap between the two tells you how uneven your errors are.
Note
Reporting a correlation (\(R\)) or \(R^2\) between predicted and observed values is common, but it is not a substitute for an error measure: a prediction that is systematically ten years too high can still correlate perfectly with the truth. Report both, and be suspicious of papers that report only the correlation.
On the next page we fit these models in python — and discover what happens when we get greedy about predictors.